Adam Colton: University of Utah

meme2

Projects

spokester-2 - a world model in your browser2026

I train a tiny transformer to produce realistic RGB frames conditioned on depth and optical flow. I use an improved training strategy to reduce flops and parameters and realism compared to spokester1. At only 17.7M parameters and 60 GFLOPs per frame, spokester-2 brings world models to your browser.
Can AI Exit Vim?2026

Most AI coding agents edit files using a diff editing toolcall, editing exact file positions. But can they enter and use Vim? And most importantly, once they enter Vim do they know how to leave? I make a simple AI agent harness where the agent operates in the full terminal buffer and directly types keypresses into the terminal. Will this succeed? Read my post to find out!

Two tools, read_term() and input(keys: string), allow AI agents to use full screen terminal programs like Vim.

Small LLMs have a Big Problem2026

The LM-head eats up 90% of the memory and compute when training small (~100m) parameter LLMs. Can I replace the LM head with a bit-diffusion head that denoises a bit-representation of the next token?

Elucidating the Role of Feature Normalization in IJEPA2025

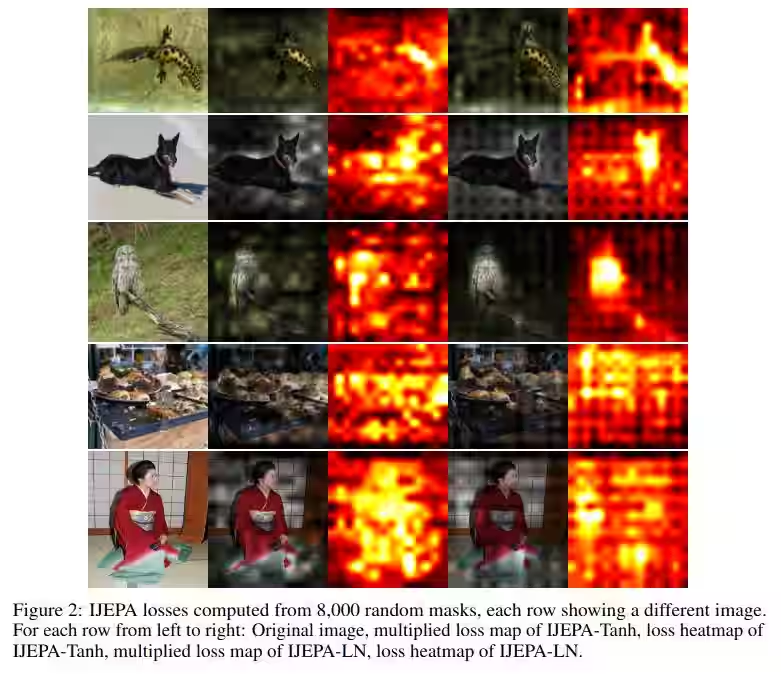
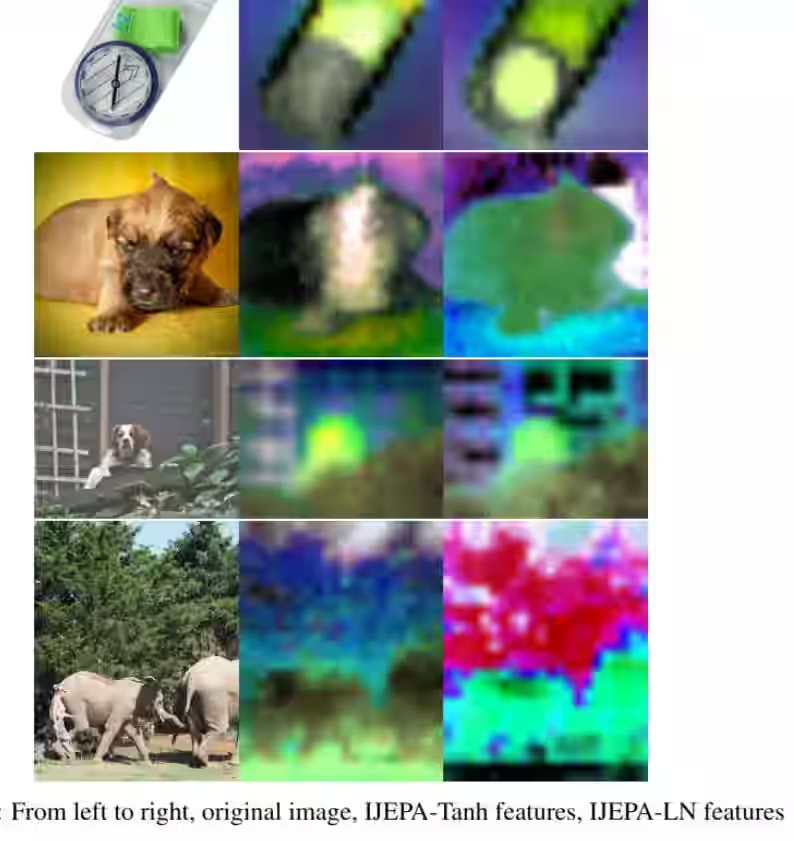
In the standard image joint embedding predictive architecture (IJEPA), features at the output of the teacher encoder are layer normalized (LN) before serving as a distillation target for the student encoder and predictor. We propose that this feature normalization disrupts the natural energy hierarchy of visual tokens, where high-energy tokens (those with larger L2 norms) encode semantically important image regions. LN forces all features to have identical L2 norms, effectively equalizing their energies and preventing the model from prioritizing semantically rich regions. We find that IJEPA models trained with feature LN exhibit loss maps with significant checkerboard-like artifacts. We propose that feature LN be replaced with a DynTanh activation as the latter better preserves token energies and allows high-energy tokens to greater contribute to the prediction loss. We show that IJEPA trained with feature DynTanh exhibits a longer-tailed loss distribution and fixes the checkerboard artifacts in the loss map. Our empirical results show that our simple modification improves ImageNet linear probe accuracy from 38% to 42.7% for ViT-Small and reduces RMSE by 0.08 on NYU Depth V2 monocular depth estimation. These results suggest that preserving natural token energies is crucial for effective self-supervised visual representation learning.

A Theory for Coupling Generation and Compression2024

I formalize two-stage generation as a bilevel optimization problem and offer a theory to improve the alignment between stage 1 models (VAEs, VQGANs, tokenizers) and stage 2 models (Diffusion, autoregressive, or other generative models).

Image Self Supervised Learning (SSL) on a Shoestring2024

I create a technique for quickly training self supervised image encoders on a single GPU. I optimize for training throughput. The code allows you to train a ViT-S at a rate of 1300 medium sized images per second.

IJEPA-Enhanced uses masked latent prediction to train a machine learning model how to 'see'.

Generative modelling of compressed image file bits2024

Do you have issues with achieving GPU saturation because of your dataloading load? Don't you wish you could train directly on compressed image files? Say no more! I trained llama to directly generate the bits of a lossy image compression file format called spiht.

spiht-py2023

An implementation of the SPIHT algorithm in Rust, with Python bindings. SPIHT is a lossy image compression algorithm. Like JPG, it can reduce the amount of bits required to store images. Unlike JPG, the SPIHT bitstream can be interrupted at any point and the entire image decoded. There are no 'blocks' in the SPIHT algorithm.

Left: intermediate decoded image. Right: intermediate coefficients from the discrete wavelet transform. Bits per pixel (BPP) are shown in the top left corner. As BPP increases, you can see how the encoder assigns information to coefficients at higher frequencies.

Your VAE Sucks2023

A short foray into the Fourier transform, JPG, Image Autoencoders, and a new image-autoencoder architecture inspired by jpg, that produces latent codes with a left-to-right positional bias.

LLMs and faithfulness to reasoning2023

Humans have written a trove of step-by-step explanations and proofs. These exist on the internet, and some of them end up in the pre-training data for large language models. Thus, some modicum of step-by-stepedness exists in the weights of LLMs....

VQ-CLIP2023

So, you've heard about CLIP, but have you heard about CLIP but with a quantized embedding space??

Rather than using a real number vector as the embedding, VQ-CLIP uses a list of k integer class IDs. The embedding codes from these models can be used for exciting downstream tasks, such as autoregressive CLIP embedding generation.

Image Retrieval: A Picture is worth 8x8x8 Words2023

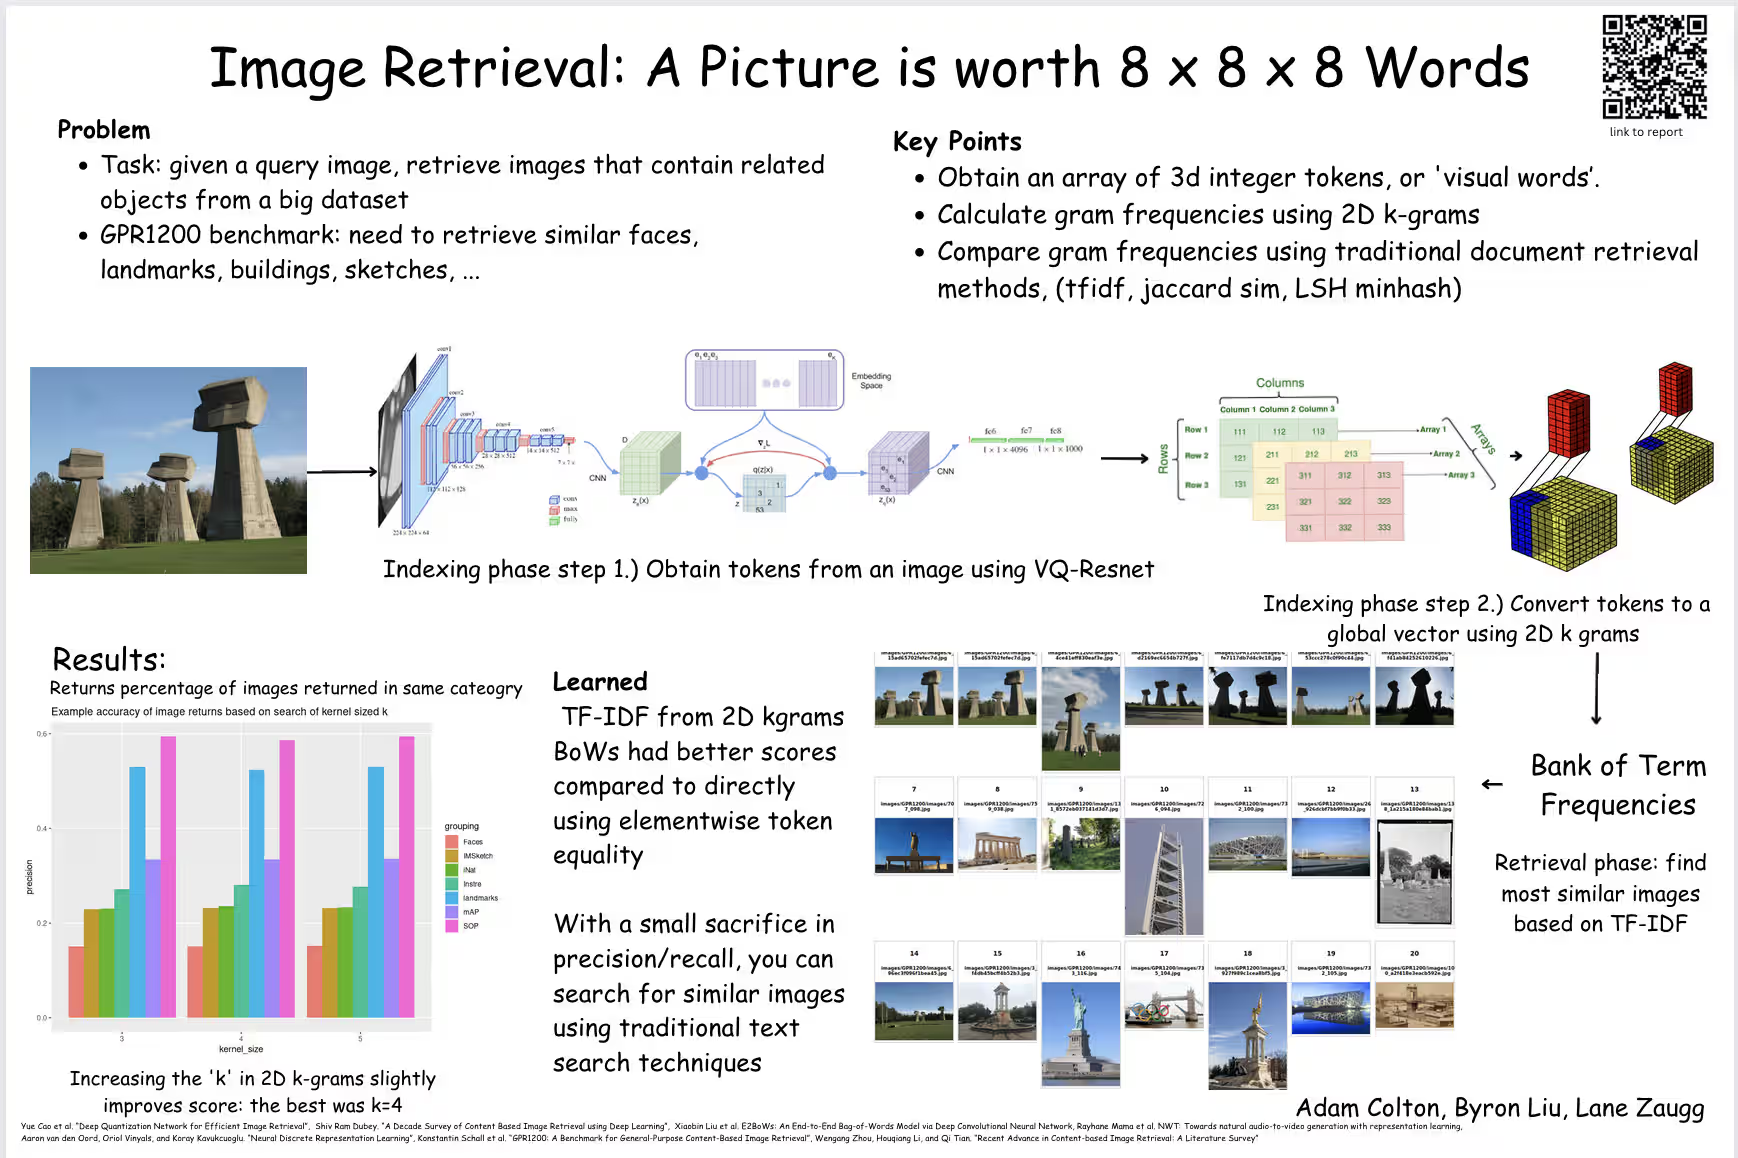
SOTA image retrieval models usually use global real-number embeddings, obtained from big neural networks. But why is there no love for more traditional information retrieval techniques such as BoW? Given a 256x256 image, we encode it into a 8x8x8 matrix of discrete integer tokens. We do this using a ResNet model trained with a learned vector quantization layer. Using these tokens, we use 2D Kgrams to obtain global vectors containing term frequencies.

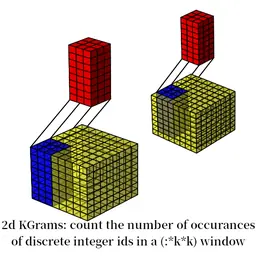
2D kgrams can be used to produce global representations which capture spatial relationships

Ascii Art Latent Masked Transformer Model2022

I trained a variational quantized autoencoder on ASCII art. The characters in the art are represented as one hot encoded vectors at each 'pixel' in the string. The discrete latents learned by this model were used to train a bidirectional transformer. The transformer was trained to predict masked latent tokens, akin to MaskGit by Google research.

Interpolation of the latent space. The top left corner shows the discrete tokens. The left ascii art is the decoded representation of the current embedding. On the right is the original.

Gravity Market2022

A D3 javascript web app which uses a physics simulation to display the percent change in value of various stocks from the S&P 500. This project was made for Vis for Data Science 2022 taught by Dr. Alexander Lex at the University of Utah. Source code to be added soon!

Songs from Ukraine2022

I scraped several hundred gigabytes of social media posts and analyzed the music found in them. Videos were scraped from the Telegram social media platform. Music metadata was retrieved from the videos using Shazam.

Videos were retrieved over the course of months. The scraping process was scheduled using SystemD units on a linux server. CSV metrics on the data were updated asynchronously via file changes. The code for the scraper and data processing was written in Python.

Ethminer GUI2021

A simple cross platform GUI app written in Rust for the ethminer CLI program. It includes capturing of console output from the program, and asynchronous channel communication using Tokio.

Adventures